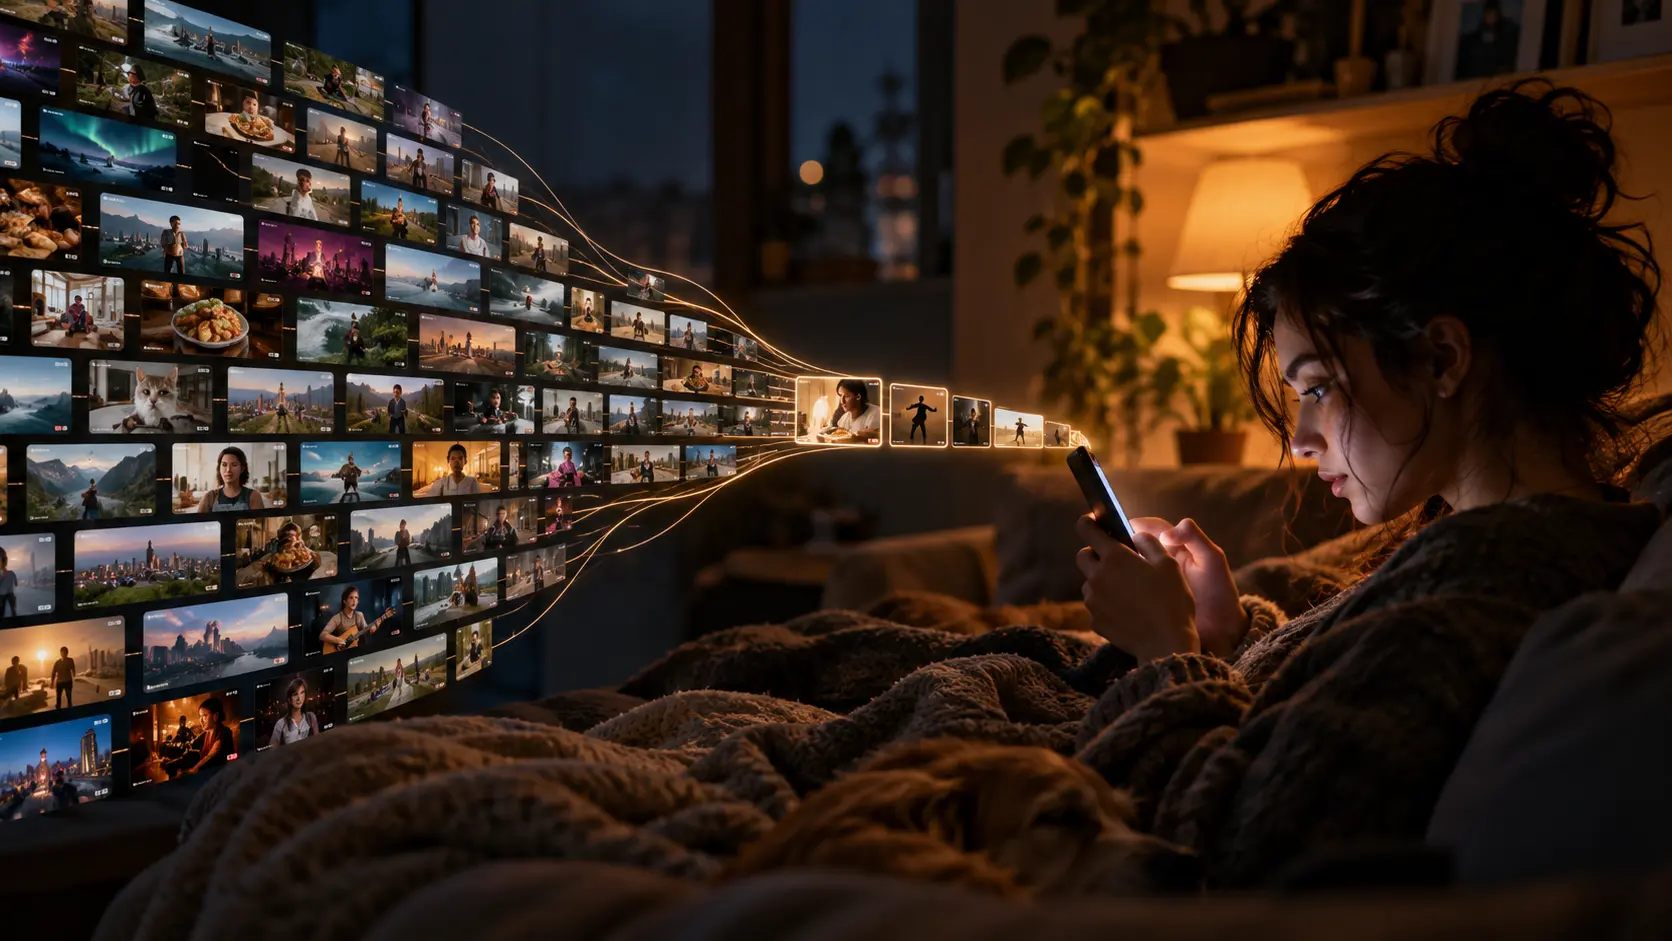
Recommendation algorithms are systems designed to choose which pieces of content a user is most likely to find relevant from an enormous pool of possibilities. On platforms such as YouTube, TikTok, Instagram, Facebook, streaming services, online stores, and news apps, there are far too many videos, posts, products, and articles for anyone to browse manually. Recommendation systems solve this problem by predicting what each person may want to see next and ranking available options accordingly.
Understanding how recommendation algorithms work begins with one basic idea: they do not usually search for a single perfect piece of content. Instead, they estimate the relative usefulness or attractiveness of many possible items and place the most promising ones near the top. This ranking process can happen every time a user opens an app, refreshes a feed, finishes a video, performs a search, or interacts with content.
To make these predictions, platforms collect signals about user behavior. These signals can include what someone watches, how long they watch, what they skip, what they like, save, share, comment on, search for, or follow. The system may also consider whether a user returns to similar topics, whether certain videos are watched to completion, and whether interaction changes over time.
Not every signal has the same meaning. Watching a video for a few seconds and immediately leaving may indicate weak interest, while watching most of it can suggest stronger interest. Saving a post may indicate a different kind of value from simply liking it. Sharing content with another person can be another strong signal because it suggests the content was important enough to pass along.
Platforms may also use information about the content itself. A recommendation system can analyze titles, descriptions, hashtags, categories, audio, visual features, language, topics, and other metadata. Modern machine learning systems can also create numerical representations of content that help identify similarities between videos, posts, products, or songs even when they are not described with exactly the same words.
The system then combines information about the user with information about the available content. One common approach is to identify items that appeal to people with similar behavior. If many users who enjoy one type of video also tend to watch another type, the system can use that pattern to make recommendations. This general idea is often associated with collaborative filtering.
Another approach focuses more directly on content similarity. If someone repeatedly watches videos about home cooking, a platform may recommend other videos with similar themes, creators, ingredients, or styles. In practice, large recommendation systems usually combine many methods rather than relying on a single technique.
Machine learning allows these systems to identify patterns that would be extremely difficult to write as simple rules. Engineers train models using large amounts of historical interaction data. The models learn relationships between users, content, context, and outcomes such as clicks, watch time, purchases, or shares. When a new recommendation is needed, the system estimates which items are most likely to produce the desired outcome.
At very large platforms, recommendation often happens in stages. The first stage retrieves a manageable set of possible items from a much larger collection. Instead of comparing a user with every video or post on the platform, the system may quickly select a few hundred or a few thousand plausible candidates. A more sophisticated ranking model can then score these candidates and decide which ones should appear first.
This process has to happen very quickly. A social media platform may have billions of pieces of content and millions of active users. Each person can have a different history and context, yet the feed is expected to appear almost instantly. Recommendation infrastructure therefore depends on powerful computing systems, fast databases, machine learning models, and carefully optimized software.
Context can influence rankings as well. A person may behave differently depending on the time of day, the device being used, the language of the content, or the type of session. Someone who watches long educational videos on a desktop computer may prefer shorter entertainment clips on a phone. Recommendation systems can learn these differences and adjust accordingly.
The objective of the platform is particularly important because recommendation algorithms optimize for goals chosen by the company. A system designed to maximize clicks may behave differently from one designed to maximize total watch time. A system optimized for purchases will make different choices from one optimized for long-term user satisfaction.
This is why the phrase “the algorithm wants” can be misleading. An algorithm does not have personal desires. It follows mathematical objectives and constraints created by designers and adjusted through experimentation. If a platform rewards a model for increasing viewing time, the system will tend to favor content that it predicts will keep people watching.
Platforms rarely optimize for only one metric. They may consider a mixture of watch time, completion rates, likes, dislikes, comments, shares, survey responses, session length, return visits, creator quality, safety, and other factors. They may also introduce rules that prevent certain types of content from being recommended even if the system predicts strong engagement.
The details of these systems are generally proprietary. Companies sometimes publish broad explanations of how their recommendation systems work, and researchers can study observable behavior, but outsiders do not normally have access to the complete ranking models, internal weights, real-time experiments, or all the signals used by platforms such as YouTube or TikTok. It is therefore possible to explain the general mechanisms of recommendation without pretending that the full operation of any specific platform is publicly known.
This distinction matters because recommendation systems are constantly changing. Platforms regularly update models, add new safety rules, adjust business objectives, and run experiments on different groups of users. A ranking factor that matters strongly at one moment may become less important later.
Personalization is powerful because it reduces the effort required to find relevant material. A user interested in photography can quickly encounter camera reviews, editing tutorials, and photographers they have never seen before. A music listener can discover artists with similar styles. An online shopper can find products related to previous purchases without searching through thousands of categories.
The same mechanism also shapes what users do not see. A recommendation system must exclude almost everything in order to select a relatively small number of items. This means ranking systems are not merely organizing information; they are also controlling visibility. Content placed near the top of a feed may receive enormous attention, while similar content placed much lower may receive almost none.
This gives platforms significant influence over information distribution. A newspaper editor traditionally decides which stories deserve prominent placement, but social media platforms perform a similar filtering function at enormous scale through automated ranking. The difference is that each user can receive a different selection.
Personalization can therefore create highly individualized information environments. Two people following many of the same accounts may still see different feeds because their previous behavior suggests different interests. Over time, these recommendations can influence what topics each person encounters regularly.
The feedback loop is an important part of this process. Recommendations influence user behavior, and that behavior becomes new data for future recommendations. If a platform shows someone more content about a particular subject and the person watches it, the system may interpret that behavior as additional evidence of interest and show even more of the same type.
This does not mean the system can perfectly determine what a person truly wants. User behavior is ambiguous. Someone may watch a disturbing video because it is surprising rather than enjoyable. A person may click on a controversial post out of curiosity rather than agreement. Recommendation models work with observable behavior, not direct access to a person's intentions.
For this reason, platforms often try to distinguish between immediate engagement and longer-term satisfaction. A piece of content may attract many clicks but leave users dissatisfied. Companies can use surveys, negative feedback, repeated usage patterns, or other signals to estimate whether recommendations are genuinely useful rather than merely attention-grabbing.
The relationship between recommendation and attention is especially important on social media. Platforms compete for limited user time. Content that keeps people watching, scrolling, or interacting can increase advertising opportunities and strengthen engagement with the service. This creates an economic incentive to build highly effective ranking systems.
However, optimizing attention can produce unintended effects. Content that is emotionally intense, surprising, controversial, or sensational may sometimes generate strong engagement. If a ranking system rewards those reactions too heavily, it can amplify material that receives attention for reasons unrelated to quality or reliability.
Platforms can counter this by modifying their objectives and adding safety or quality controls. They may reduce the reach of spam, misinformation, repetitive content, or material considered harmful under platform rules. They can also increase the visibility of authoritative sources in certain contexts. These decisions are not purely technical because they involve judgments about what the system should prioritize.
Recommendation also influences creators. Once creators understand that certain formats, topics, thumbnails, posting schedules, or video lengths tend to perform well, they may adapt their work to the platform. This means the algorithm does not merely sort existing content; it can indirectly influence what kind of content gets produced.
The effect can be positive when recommendation helps small creators reach interested audiences without needing large advertising budgets. A new creator can sometimes gain significant visibility because the system detects that viewers respond well to the content. At the same time, creators can become dependent on unpredictable ranking systems whose internal rules they cannot fully see.
The same principles apply outside social media. E-commerce platforms recommend products based on browsing, purchases, ratings, and similarities between customers. Streaming services recommend films and music based on viewing or listening history. News apps rank articles according to predicted relevance. Dating platforms, travel sites, and online learning services also use forms of recommendation.
Different objectives produce different experiences. A shopping site may prioritize the probability of purchase, expected revenue, or customer satisfaction. A video platform may emphasize watch time and return visits. A news service may combine relevance, freshness, source quality, and diversity. The general technology can be similar while the resulting behavior differs because the goals are different.
Recommendation systems must also address what is known as the cold-start problem. A new user has little or no history, so the platform does not yet know their preferences. A new piece of content may also have very few interactions. In these cases, the system may use general popularity, basic profile information, content features, location, language, or exploratory recommendations to gather more information.
Exploration is necessary because a system that only recommends things similar to what a person already consumes can become too narrow. Platforms often deliberately introduce unfamiliar content to test whether the user might enjoy it. This balance between exploiting known preferences and exploring new possibilities is a fundamental challenge in recommendation.
Diversity can also be an explicit design goal. A platform may avoid showing ten nearly identical items in a row even if all of them receive high predicted scores. It may mix topics, creators, formats, or levels of popularity to make the feed more useful and less repetitive.
Privacy is another major issue because personalization depends on data. The more a platform knows about user behavior, the more accurately it may be able to predict interests. At the same time, collecting detailed behavioral information raises questions about how that data is stored, combined, protected, and used.
Users may also assume recommendation systems know more about them than they actually do. In reality, these systems often make statistical predictions rather than building a complete psychological understanding of each individual. A model may infer that a person is likely to watch a particular type of video without knowing why that person is interested in it.
Even so, the scale of these predictions gives platforms substantial power. A recommendation algorithm can determine which creators receive visibility, which products gain sales, which political messages spread widely, and which cultural trends accelerate. Small differences in ranking can have large consequences when applied to millions of users.
This is why recommendation systems have become part of wider debates about competition, media influence, transparency, and platform responsibility. When a few digital platforms control access to enormous audiences, their ranking decisions can affect public discussion as well as commercial success. The design of these systems therefore has consequences beyond convenience.
Greater transparency can help users and regulators understand the broad principles shaping feeds, but complete transparency is difficult. Recommendation models can contain huge numbers of parameters and interact with many business rules. Even engineers may find it challenging to explain every individual recommendation in simple terms.
The most useful way to understand how recommendation algorithms work is therefore to see them as large prediction and ranking systems. They collect signals about users and content, generate possible recommendations, estimate which options best match the platform's objectives, and continuously learn from new interactions. Their exact implementation differs across companies and is often not fully public.
What appears on a social media feed is not a neutral sample of everything available. It is the result of repeated automated decisions about relevance, engagement, safety, commercial priorities, and user preferences. Recommendation algorithms make digital platforms easier to navigate, but they also shape attention and determine which information becomes visible. That combination of convenience and influence is what makes them one of the most important technologies behind modern social media.