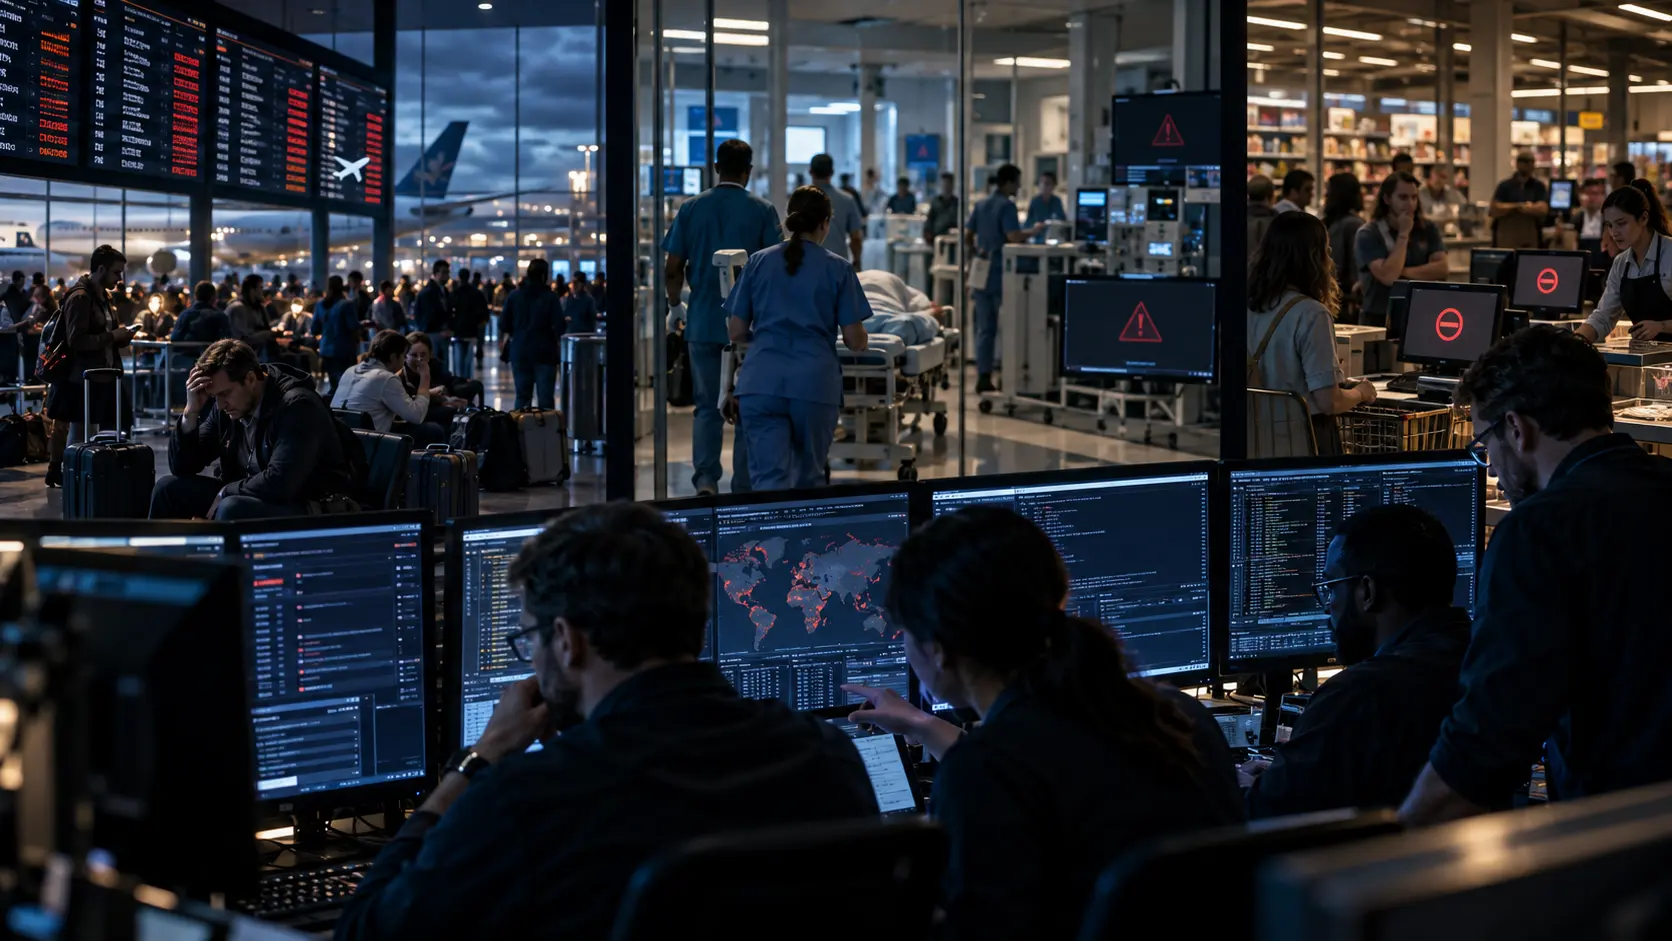
Cloud outages can disrupt far more than a single website or application. Because many businesses, governments, financial services, communication tools, and consumer platforms rely on shared cloud infrastructure, a failure at one provider can affect thousands of organizations at the same time. What appears to users as several unrelated problems may actually come from the same underlying technical failure.
The cloud is built on physical infrastructure: data centers, servers, storage systems, networks, power supplies, software platforms, and identity services. Companies rent or consume these resources instead of operating everything themselves. This creates efficiency and flexibility, but it also creates dependency. When a critical layer becomes unavailable, every service that relies on it may be affected.
A cloud outage can begin in many ways. A software update may introduce an error, a network configuration may fail, a power problem may affect a data center, or an internal control system may stop functioning correctly. Even if the original problem is small, the consequences can spread quickly because modern services are highly interconnected.
This is where cascading failures become important. A cascading failure occurs when one problem triggers another, which then causes further disruption. For example, if a cloud networking service fails, applications may lose access to databases. Those applications may then stop processing payments or customer requests. Monitoring systems may generate large numbers of alerts, while automatic recovery mechanisms create additional traffic and increase pressure on the remaining infrastructure.
The result can be a chain reaction in which several systems fail even though only one component was initially affected. This is especially likely when many services depend on the same shared infrastructure.
The dependencies are often invisible to users. A retailer may use one cloud provider for its website, another company for payments, a separate service for authentication, and an external messaging platform for customer notifications. Those providers may themselves depend on additional cloud, networking, or software services.
This means one application can rely on a long chain of suppliers. If any critical link becomes unavailable, the end user may simply see an error message without knowing where the actual failure occurred. The application itself may be functioning correctly while one of its dependencies is not.
Authentication systems are a good example. Many digital services depend on centralized identity platforms to verify users. If the identity service goes down, people may be unable to log in even though the application servers and databases remain fully operational. A failure in one shared service can therefore make many otherwise healthy systems inaccessible.
Payment systems can experience similar problems. An online store may continue displaying products, but purchases can fail if the payment processor, banking connection, fraud-detection service, or cloud database becomes unavailable. In physical stores, cloud-dependent point-of-sale systems can also be affected if they cannot reach remote services.
Communications platforms create another form of dependency. Companies often rely on cloud-based email, messaging, video conferencing, and collaboration tools. If one of these services fails during a wider technical incident, employees may lose the very systems they would normally use to coordinate the response.
This is one reason major outages can feel unusually disruptive. The affected service may not be the only problem. The tools needed to communicate, monitor, authenticate, or recover may depend on the same infrastructure.
Enterprise systems are equally exposed. Companies use cloud platforms for inventory management, accounting, customer databases, analytics, human resources, logistics, and software development. A significant outage can therefore interrupt internal business operations even if the company's public website remains online.
Manufacturing and logistics can also be affected. Warehouses may depend on cloud systems for inventory data, routing, barcode processing, or automated equipment. Factories may rely on remote applications for scheduling and production management. If those systems become unavailable, digital disruption can begin to affect physical operations.
Financial services face especially high availability requirements because even short interruptions can have large consequences. Banks, trading platforms, payment processors, and financial technology companies depend on continuous access to computing and networking systems. A cloud outage can delay transactions, prevent account access, or interrupt internal processing.
Modern companies try to reduce these risks through redundancy. Redundancy means maintaining extra resources so that the failure of one component does not stop the entire service. A system may use multiple servers, storage copies, network connections, or data centers.
Within a cloud region, applications can often be distributed across separate availability zones. These zones are designed so that a failure in one location does not necessarily affect another. If one zone becomes unavailable, traffic can be redirected to systems elsewhere.
However, redundancy only works when the backup systems are genuinely independent. Two applications may appear to run in different locations but still depend on the same identity service, control plane, network backbone, or database. A shared dependency can undermine the protection that redundancy was supposed to provide.
Geographic redundancy goes further by operating systems in different regions. If one region experiences a major outage, another can take over. This can improve resilience, but it also increases cost and complexity.
Databases must be synchronized, user sessions may need to be transferred, and routing systems must know when to redirect traffic. Engineers must also make decisions about how much data loss is acceptable during a failure and how quickly service must be restored.
These questions are usually expressed through recovery objectives. The recovery time objective refers to how quickly a system should return after an interruption. The recovery point objective describes how much recent data the organization can afford to lose.
A critical payment system may require very short recovery times and minimal data loss. A less important internal application may tolerate a longer outage. Designing all systems for near-perfect availability would be extremely expensive, so organizations prioritize according to business impact.
Backups are another important part of resilience, but they solve a different problem from redundancy. Redundancy helps keep a service running when components fail. Backups help restore information after data is corrupted, deleted, or lost.
A company can have highly redundant infrastructure and still be vulnerable if corrupted data is copied across every redundant system. Reliable backups therefore need to be protected, tested, and separated enough from production systems to survive major incidents.
Disaster recovery plans combine these techniques. They define what should happen when normal operations cannot continue. This can include switching to another region, restoring databases, activating backup communication channels, or temporarily operating with reduced functionality.
The existence of a recovery plan is not enough by itself. Organizations must test whether it works. A backup that has never been restored or a failover system that has never been exercised may fail during a real incident.
Resilience also involves reducing unnecessary dependencies. Some applications are designed so that every feature depends on a large number of external services. Others can continue operating in a limited mode when one component is unavailable.
A retailer, for example, may design systems so customers can continue browsing products even if personalized recommendations fail. A payment terminal might support limited offline processing under certain conditions. This idea is known as graceful degradation: the service loses some capabilities but does not fail completely.
Multi-cloud strategies are sometimes used to reduce dependence on one provider. An organization may distribute applications across two or more cloud companies. In theory, this can protect against a major failure at one provider.
In practice, multi-cloud resilience is difficult. Cloud platforms use different technologies, management systems, databases, and security tools. Building an application that can move seamlessly between them can require substantial engineering work. Companies may also lose some of the efficiency gained from using provider-specific services.
For this reason, simply using multiple cloud providers does not automatically make a company resilient. The most important question is whether critical dependencies have actually been separated.
Network connectivity is another major vulnerability. A cloud application may be running normally, but users cannot reach it if internet connections, routing systems, or telecommunications networks fail. Companies therefore need to consider connectivity as part of cloud resilience rather than treating it as a separate issue.
Domain name systems can also create widespread disruption. If a DNS service fails, users may be unable to find the correct network address for an application even though the servers are still running. Because DNS is such a fundamental layer of internet communication, problems there can make many services appear offline.
Control systems inside cloud platforms can have similarly broad effects. Cloud providers use centralized software to manage infrastructure, deploy resources, control permissions, and coordinate networks. If these systems fail, customers may be unable to create or modify resources even when existing servers continue operating.
This distinction between the data plane and the control plane is important. The data plane handles actual user traffic and application data. The control plane manages how infrastructure is configured. An outage affecting one may have different consequences from an outage affecting the other.
Large providers invest heavily in preventing these problems. They operate redundant data centers, backup power systems, global networks, automated monitoring, and teams dedicated to reliability. Cloud platforms can often be more resilient than infrastructure that individual companies could build on their own.
The problem is that concentration changes the scale of failure. If a small company's private server fails, the impact may be limited to that organization. If a major cloud platform experiences a widespread outage, the same event can affect thousands of businesses and millions of users.
This is the central structural risk of cloud dependence. Shared infrastructure creates efficiency during normal operations, but it can also create shared points of failure.
Market concentration makes this issue more significant. A relatively small number of companies operate a large share of global cloud infrastructure. Many organizations therefore depend on the same providers, even if they are in completely different industries.
This concentration can create correlated risk. Banks, retailers, software companies, media platforms, and government agencies may all be affected by the same infrastructure problem at the same time.
The situation resembles other forms of critical infrastructure. Electricity grids, telecommunications networks, and payment systems provide services that many parts of the economy depend on simultaneously. Cloud infrastructure increasingly plays a similar role.
For this reason, digital availability is becoming more than an internal technology issue. It is becoming part of economic resilience. A prolonged interruption in widely used cloud services could affect commerce, communications, financial activity, transportation, healthcare, and public administration.
Governments and regulators are therefore paying more attention to operational resilience. They may require certain industries to maintain backup systems, test disaster recovery plans, or understand their dependence on external technology providers.
Financial institutions are particularly sensitive to this issue because many firms can depend on the same cloud platforms. Regulators may worry not only about whether one bank is resilient but also about whether many banks share the same technological dependency.
Businesses also need to understand the difference between contractual guarantees and actual resilience. Cloud providers often offer service-level agreements that specify expected availability. These agreements can provide financial compensation when performance falls below agreed levels, but compensation does not restore lost business during an outage.
A refund for service downtime may be small compared with the cost of missed sales, interrupted operations, or damaged customer trust. Companies therefore need technical resilience, not only contractual protection.
Monitoring is part of that resilience. Organizations need to know whether a problem comes from their own application, a cloud provider, a network operator, or another dependency. Good monitoring systems can identify failures quickly and help teams determine which components remain operational.
Observability goes further by combining logs, metrics, traces, and other technical information to show how complex systems are behaving. This is especially valuable in distributed cloud environments where one user request may pass through many services.
Incident response is equally important. During a major outage, teams need clear responsibilities, communication channels, and decision-making procedures. Technical recovery can be delayed if employees do not know who should take action or if emergency communication depends on the failed system.
Some organizations maintain separate communication channels specifically for emergencies. Others document recovery procedures outside their primary cloud environment so that instructions remain accessible even if that platform is unavailable.
Human decisions can also contribute to outages. Many major failures are not caused by hardware breaking but by configuration changes, software updates, or automation behaving unexpectedly. Modern cloud systems are so complex that a small mistake can sometimes spread rapidly.
Automation helps manage large infrastructure, but it can also accelerate errors. A faulty change that would once have affected one server may now be deployed to thousands of systems within minutes. This is why cloud operators use staged rollouts, testing environments, change controls, and automatic rollback mechanisms.
Resilience therefore depends on both technology and organizational discipline. Redundant hardware is useful, but so are careful software deployments, clear procedures, regular testing, and realistic assumptions about what can fail.
The goal is not to eliminate every outage. Perfect availability is practically impossible. Instead, resilient systems are designed to limit the impact of failures and recover quickly.
This involves asking uncomfortable but necessary questions. What happens if an entire cloud region disappears? What if the identity service is unavailable? What if employees cannot access the normal communication system? What if several suppliers fail at once?
Organizations that consider these scenarios before an incident are better prepared to respond when something unexpected happens.
Cloud outages reveal how deeply digital services have become integrated into everyday economic activity. A failure in shared infrastructure can interrupt payments, communications, business operations, and consumer services even when the affected organizations have done nothing wrong themselves.
The risks come from interconnected dependence. Modern digital systems are built from layers of cloud platforms, networks, APIs, identity providers, databases, and external services. Each layer improves efficiency and functionality, but each can also become a point where disruption spreads.
Digital resilience therefore requires more than keeping servers online. It requires redundancy, tested recovery plans, protected backups, independent communication channels, careful dependency management, and systems that can continue operating in reduced form when necessary.
Cloud outages are ultimately a reminder that convenience and dependence grow together. The cloud makes enormous computing resources available on demand, but the more economic activity depends on a small number of interconnected platforms, the more important their availability becomes. In a digitally dependent economy, resilience is no longer just a technical feature. It is part of the infrastructure that allows commerce, communication, and essential services to continue functioning.