Large language models are artificial intelligence systems trained to recognize and generate patterns in language. They power many modern tools that can answer questions, summarize documents, write code, translate text, explain concepts, and hold extended conversations. Their fluency can make them seem as though they understand language in the same way people do, but their underlying operation is very different. To understand how large language models work, it helps to examine how they represent text, how transformer architectures process information, how training shapes their behavior, and how prediction can produce surprisingly complex forms of reasoning.
The first step is tokenization. A language model does not read text as complete sentences in the way a human reader does. Instead, the text is divided into smaller units called tokens. A token may be an entire word, part of a word, punctuation, a number, or another symbol. Common words may appear as single tokens, while rare or complicated words may be split into several pieces. This approach allows a model to work with a manageable vocabulary while still representing an enormous variety of expressions.
Once text has been converted into tokens, each token is transformed into a numerical representation called an embedding. An embedding is a set of numbers that places the token in a mathematical space where relationships can be represented. Tokens that appear in similar contexts can develop related numerical patterns, allowing the model to capture useful associations between words and concepts. The representation of a word also depends on context, which is essential because the same word can mean different things in different sentences.
The architecture that made modern large language models possible is the transformer. Introduced as a way to process sequences efficiently, transformers are particularly good at identifying relationships between different parts of a text. Earlier language systems often processed words mainly in order, which made it more difficult to handle long-range relationships. Transformers can compare many parts of a sequence more directly and determine which pieces of information are most relevant to one another.
The central mechanism behind this capability is called attention. Attention allows the model to assign different levels of importance to different tokens while processing a sequence. Consider a sentence containing several people, objects, and pronouns. To interpret what a pronoun refers to, the model needs to identify which earlier words are relevant. Attention provides a mathematical way to make those connections. Instead of treating every previous token as equally important, the model calculates relationships and gives greater weight to the information that appears most useful.
Modern transformers usually use multiple attention mechanisms at the same time. These are often called attention heads. Different heads can learn to focus on different kinds of relationships, such as grammatical structure, word associations, references between distant parts of a sentence, or patterns connected to meaning. The model combines these signals across many layers, progressively constructing richer representations of the text.
Position also matters. Because attention mechanisms do not automatically know which token came first, transformers include information about where tokens appear in a sequence. This positional information allows the model to distinguish between sentences containing the same words in different orders. Word order can completely change meaning, so representing sequence structure is essential for reliable language processing.
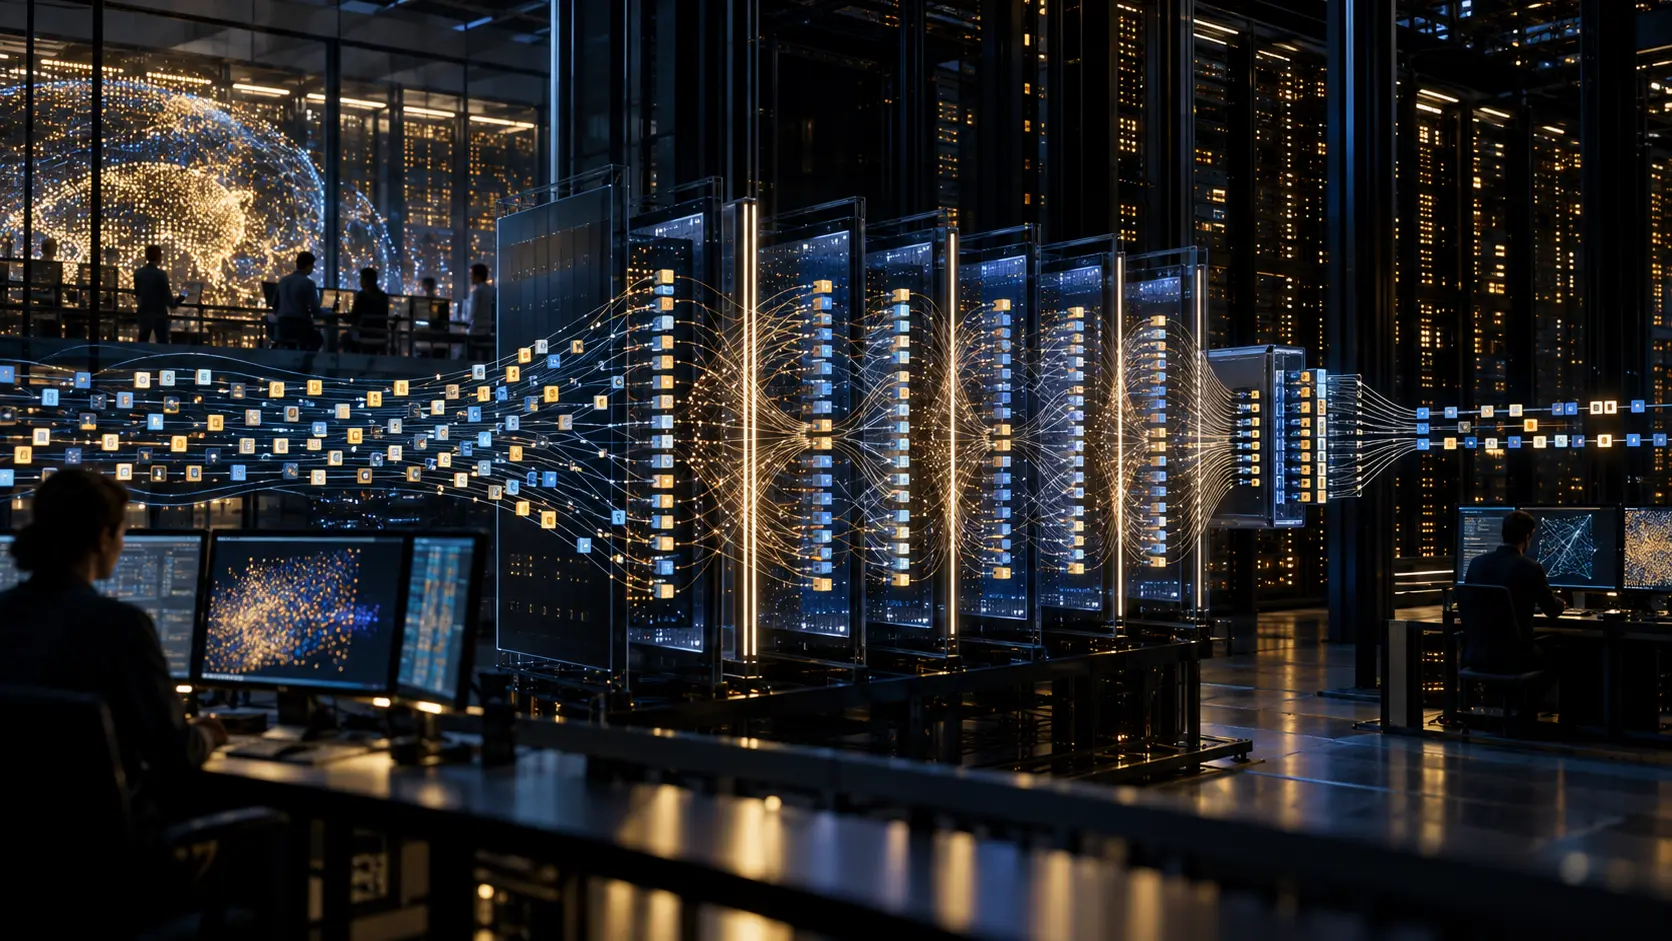
A large language model contains many transformer layers stacked together. Each layer receives numerical representations from the previous layer, processes relationships among tokens, and produces a refined representation. Early layers may capture relatively simple features, while deeper layers can represent more complex patterns involving syntax, context, topics, relationships, and abstract concepts. The exact internal organization is difficult to interpret completely, but the overall result is a system capable of modeling very complex regularities in language.
The word “large” refers partly to the number of parameters in the model. Parameters are adjustable numerical values learned during training. They influence how strongly different pieces of information affect one another and how the model transforms inputs into predictions. Modern language models can contain billions of parameters, although size alone does not determine quality. Training data, architecture, optimization methods, and additional refinement all contribute to performance.
Training usually begins with a simple objective: predict missing or upcoming parts of text. In many language models, the system receives a sequence of tokens and tries to predict the next token. It then compares its prediction with the actual token in the training data and adjusts its parameters slightly to improve future predictions. This process is repeated across enormous amounts of text.
At first, the model performs poorly. As training continues, however, it begins to learn recurring patterns. It learns that certain words tend to follow others, that grammatical structures have regular forms, that concepts appear in characteristic contexts, and that different styles of writing follow recognizable conventions. Because accurate next-token prediction requires sensitivity to many aspects of language, the model gradually develops representations that support much more than simple word completion.
For example, predicting the next token in a scientific explanation may require recognizing the topic, understanding the relationship between technical terms, tracking what has already been stated, and maintaining the structure of the argument. Predicting dialogue may require modeling tone, intent, conversational context, and likely responses. Predicting computer code may require following programming syntax and understanding relationships between variables and functions. A relatively simple training objective can therefore lead to surprisingly broad capabilities.
The scale and diversity of training data are important because language contains information about much more than grammar. Written material includes descriptions of science, history, culture, law, mathematics, everyday behavior, fiction, software, and countless other subjects. By learning patterns across these sources, a model can acquire extensive statistical relationships between concepts. It does not simply memorize a dictionary of facts; it builds a distributed representation in which knowledge is encoded across many parameters.
This helps explain why large language models can generate convincing explanations. When prompted with a question, the model uses the prompt as context and estimates which sequence of tokens is most appropriate to follow. Because its training exposed it to many examples of explanations, arguments, definitions, examples, and instructional writing, it can reproduce the structural patterns that make an explanation coherent. It can introduce a concept, define terms, connect causes and consequences, and provide examples because those patterns have been learned from language.
Generation happens one token at a time. After the model predicts a possible next token, that token is added to the existing sequence and becomes part of the context for the next prediction. The process continues until the response is complete. The model does not normally plan every sentence of an answer in advance. Instead, it repeatedly updates its predictions based on everything that has already been generated.
The system does not always choose the single most probable token. Generation methods can introduce controlled randomness, allowing the model to select from several plausible possibilities. This is why the same prompt can produce different responses. Adjusting this randomness changes how predictable or varied the output becomes. Lower randomness tends to produce more consistent results, while higher randomness can produce more diverse but sometimes less reliable language.
After initial training, many language models go through additional stages designed to make them more useful. They may be trained on examples of instructions and appropriate responses so that they learn to follow user requests more effectively. Developers may also use human feedback or other evaluation methods to encourage helpful behavior, discourage unsafe outputs, and improve conversational quality. These later stages do not replace the original language modeling process, but they shape how the trained model behaves when interacting with users.
One of the most debated questions is whether large language models can reason. They clearly can perform tasks that resemble reasoning, including solving some mathematical problems, analyzing arguments, comparing alternatives, writing and debugging code, and following multi-step instructions. In some cases, performance improves when a model is given more time or computational resources to work through a problem.
This does not mean that machine reasoning is identical to human reasoning. Human thought is connected to perception, memory, physical experience, emotion, goals, social interaction, and conscious awareness. Language models operate through numerical transformations over learned representations. Their reasoning abilities emerge from patterns in training, model architecture, and inference rather than from a biological mind experiencing the world.
It is also misleading to describe a language model as merely repeating memorized text. Models can often solve unfamiliar problems, apply known patterns in new combinations, and produce outputs that were not present in their training data. Generalization is a central reason they are useful. However, generalization is not unlimited. A model may perform well on problems that resemble structures encountered during training while struggling with unusual situations or tasks requiring precise knowledge that it has not learned.
The distinction between statistical processing and understanding is therefore more subtle than a choice between “thinking” and “not thinking.” Large language models clearly represent complex relationships and can manipulate those representations in useful ways. They can connect ideas, detect analogies, infer patterns, and produce coherent arguments. At the same time, these capabilities do not establish that they possess human-like comprehension, consciousness, intentions, or lived experience.
Their statistical nature also explains an important weakness: hallucination. A model is optimized to generate plausible continuations, not automatically to verify that every statement is true. If the learned patterns strongly support a convincing answer but the required facts are missing or uncertain, the model may generate incorrect information with confident wording. This can include invented dates, sources, quotations, names, or explanations.
Connecting language models to external tools can reduce this limitation. A model may use a search system to retrieve current information, a calculator to perform exact arithmetic, a database to obtain verified records, or software tools to carry out actions. In these systems, the language model provides interpretation and decision-making while external resources provide information or capabilities that the model itself does not reliably contain.
Context windows also influence how language models work. A context window is the amount of information the model can consider at one time during a conversation or task. A larger context window allows the system to work with longer documents, more extensive conversations, or larger collections of data. However, simply fitting more text into the context does not guarantee perfect recall or understanding. The model still has to identify which parts are relevant and use them correctly.
Another limitation comes from the quality of the training material. If training data contains mistakes, stereotypes, contradictions, or uneven representation, the model can learn those patterns as well. Developers can apply filtering, additional training, safety systems, and evaluation procedures to reduce these problems, but no large dataset perfectly represents reality.
Large language models can also struggle with reliability across complicated multi-step tasks. A small error in one stage of reasoning can influence later stages, and a model may fail to recognize that it has made a mistake. This is one reason advanced systems increasingly combine language models with verification methods, external tools, structured workflows, and AI agents that can inspect intermediate results.
Despite these limitations, large language models represent a major advance in artificial intelligence because of the breadth of tasks they can perform using a common architecture. The same underlying system may be able to write prose, explain science, translate languages, analyze code, summarize contracts, or assist with planning. This flexibility comes from learning general patterns across enormous amounts of language rather than being programmed separately for every task.
So, how do large language models work? They convert language into tokens, transform those tokens into numerical representations, process relationships through transformer layers and attention mechanisms, and generate new sequences by predicting what should come next. Training across very large datasets allows them to acquire complex linguistic and conceptual patterns, while later refinement makes them better at following instructions and interacting with users.
Their abilities can look remarkably close to human reasoning, especially when they explain ideas clearly or solve unfamiliar problems. Yet the mechanisms remain different from human cognition. Large language models are powerful statistical systems capable of learning and manipulating complex representations, not digital copies of the human mind. Understanding both sides of that distinction is essential for appreciating what these systems can do, why they sometimes fail, and how their role in artificial intelligence is likely to continue evolving.