Generative artificial intelligence is a type of AI designed to create new content rather than simply classify, sort, or retrieve existing information. It can produce text, images, music, speech, software code, and increasingly realistic video. The key idea is that these systems learn statistical patterns from large amounts of training data and then use those patterns to generate outputs that resemble the kinds of material they encountered during training. Understanding how generative AI works requires looking at both what these models learn and how they turn that learning into something new.
Traditional software follows rules explicitly written by programmers. A conventional program might calculate a tax rate, sort a list, or display a specific response when certain conditions are met. Generative AI works differently. Instead of receiving a complete set of rules for every possible output, the model is trained on examples. During training, it adjusts a very large number of internal numerical values, known as parameters, so that it becomes better at recognizing relationships within the data. These parameters do not store a simple database of sentences, pictures, or sounds. Rather, they capture patterns that help the model predict what kinds of elements are likely to appear together.
In text generation, those elements are usually tokens, which are small units of text that may correspond to whole words, parts of words, punctuation, or other symbols. A language model receives a sequence of tokens and estimates which token is most likely to come next. Once it selects a token, that token becomes part of the context used to predict the following one. Repeating this process many times can produce complete sentences, paragraphs, computer programs, or longer documents.
This next-token prediction process may sound simple, but the scale of modern models makes it remarkably powerful. To predict language accurately, a model must learn many regularities in writing, including grammar, style, factual associations, common reasoning patterns, relationships between concepts, and the structure of different types of documents. If a model has encountered enough varied examples during training, it can generalize beyond exact phrases it has seen before and produce combinations that are new.
The architecture behind many modern language models is called a transformer. Transformers are particularly effective at identifying relationships between different parts of a sequence. A mechanism known as attention allows the model to weigh which earlier words or tokens are most relevant when generating the next part of a response. This helps the system maintain context, connect references across a passage, and recognize patterns that depend on information appearing far apart in the text.
Training usually begins with large datasets and an objective that rewards the model for making better predictions. The system repeatedly processes examples, compares its predictions with the actual data, measures the error, and adjusts its parameters to reduce that error. This process can require enormous computing resources because modern models may contain billions of parameters and process vast quantities of data. After this broad training stage, models can be further adapted through additional training, human feedback, or other techniques intended to make their behavior more useful, safe, and aligned with user instructions.
Image generation follows a related principle but operates on visual information rather than only text. One common approach is based on diffusion models. During training, these systems learn how to reverse a process in which noise is gradually added to an image. To generate a new picture, the model begins with random noise and repeatedly transforms it into a more structured image. When given a text prompt, the system uses the meaning represented in that prompt to guide the denoising process toward visual features that match the request.
For example, a prompt describing a red bicycle beside a lake at sunset provides several pieces of information about objects, colors, relationships, and atmosphere. The model does not retrieve a single matching photograph and copy it. Instead, it generates a new arrangement by drawing on patterns learned about bicycles, lakes, sunsets, colors, lighting, composition, and the way these concepts tend to appear together. Because the process contains an element of randomness, the same prompt can produce different images each time.
Some image models work in a compressed mathematical representation known as a latent space rather than manipulating every individual pixel directly throughout the generation process. A latent representation captures important visual features in a more compact form. Working in this space can make generation more efficient while still allowing the final output to contain detailed colors, shapes, textures, and objects.
Audio generation uses similar ideas to model patterns over time. Speech systems can learn relationships between written language and the acoustic characteristics of spoken words, including pronunciation, rhythm, tone, and pauses. Music models can learn patterns involving melody, harmony, instrumentation, structure, and timing. Depending on the design, an audio generator may predict sound representations directly or work with compressed audio tokens before converting them into a waveform that can be played.
Modern speech synthesis has advanced far beyond the robotic voices associated with older text-to-speech systems. Generative models can produce speech with changes in pacing, emotion, emphasis, and vocal character. Some systems can also imitate a specific voice from a small amount of recorded audio. This creates useful applications in accessibility, translation, entertainment, and communication, but it also introduces serious concerns about impersonation, fraud, and the creation of misleading recordings.
Video generation is especially demanding because a video must be coherent both within each frame and across time. Generating a realistic single image is not enough. Objects need to remain visually consistent as they move, people should not suddenly change appearance, lighting should remain plausible, and motion must follow believable physical patterns. Video models therefore need to represent both visual structure and temporal relationships.
Many video generation systems extend techniques used for image synthesis while adding mechanisms that account for sequences of frames. A text prompt may describe a scene, camera movement, subject, and action, and the model attempts to generate a sequence that matches those instructions. The difficulty grows rapidly as videos become longer because small inconsistencies can accumulate. Maintaining the identity of a person, object, or environment across many frames remains one of the challenges of high-quality video generation.
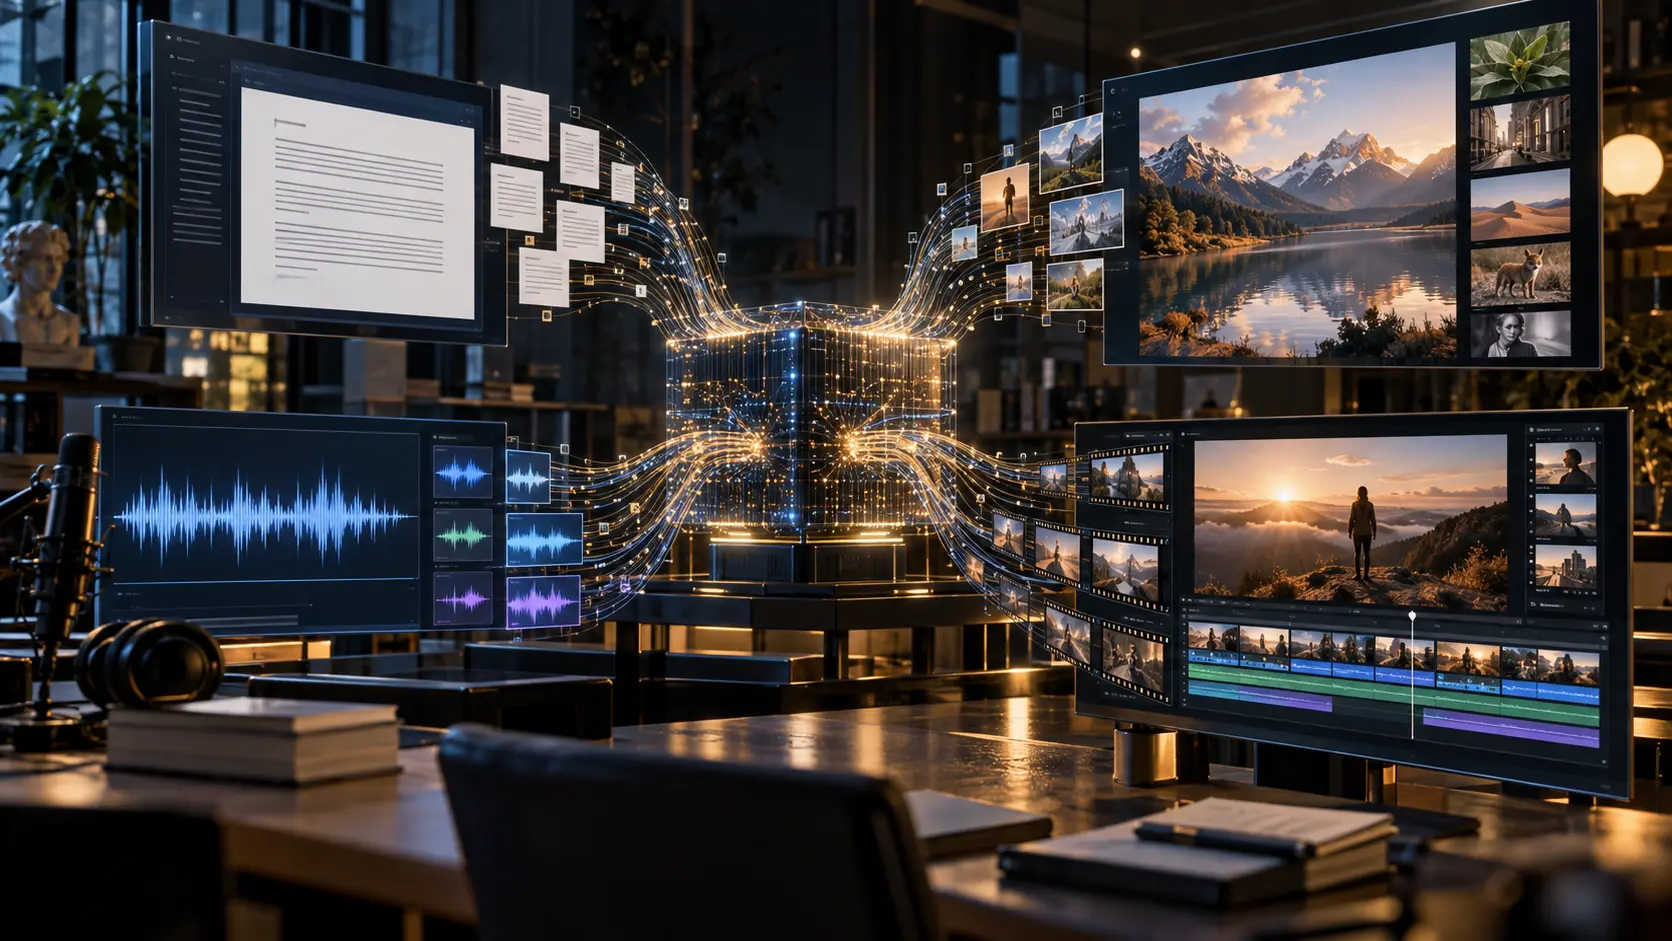
Generative AI is also becoming increasingly multimodal. A multimodal model can work with more than one type of information, such as text, images, audio, and video. Instead of treating these formats as completely separate domains, the system learns relationships between them. It may be able to look at a photograph and describe it, listen to speech and respond in text, create an image from a written description, or analyze a video while answering questions about what happened.
The development of multimodal systems is important because human communication is naturally multimodal. People do not understand the world through text alone. We combine language with vision, sound, gestures, and physical context. AI systems that can process several forms of information are therefore able to handle a wider range of practical tasks and interact with users in more flexible ways.
Despite their sophistication, generative models do not create content in the same way that humans do. A model does not need personal experience, intention, or conscious imagination in order to produce something that appears creative. Its output emerges from mathematical transformations based on patterns learned during training and the context provided at generation time. This distinction matters because fluent or realistic output can create the impression that the system understands its subject more deeply than it actually does.
A language model, for instance, can produce an accurate explanation of a scientific concept because it has learned patterns associated with how that concept is described and connected to other ideas. But it can also generate a plausible-sounding explanation that contains errors. The model is fundamentally trying to produce a continuation that fits its learned patterns and current context. It does not automatically verify every statement against an external source of truth.
This is the origin of one of the best-known limitations of generative AI: hallucination. A model may invent names, facts, quotations, citations, or events while presenting them in a confident style. Such errors occur because producing statistically plausible content is not the same as retrieving or verifying accurate information. Developers can reduce this problem by connecting models to reliable databases, search systems, calculators, specialized tools, or verification processes, but the possibility of error remains important.
Generative image, audio, and video systems have related limitations. An image may look convincing while containing physically impossible details. A generated voice may sound natural but communicate false information. A video may appear realistic even though the event never happened. As synthetic media becomes more believable, the ability to judge truth based only on appearance or sound becomes less reliable.
Another limitation involves the boundaries of the training data. Models tend to perform better on patterns that are well represented in the examples they learned from and may struggle with rare situations, unfamiliar cultural contexts, unusual combinations, or highly specialized material. Biases present in training data can also influence generated outputs. If certain groups, occupations, or situations are represented unevenly or stereotypically, the model may reproduce those patterns unless corrective techniques are applied.
Generative models can also have difficulty maintaining consistency over long or complicated tasks. A text model may contradict something it stated earlier, an image generator may struggle to place several objects exactly as requested, and a video model may lose continuity over time. More advanced architectures, larger context windows, improved training methods, external memory, and tool use can reduce these problems, but they do not eliminate them completely.
The apparent creativity of generative AI comes from its ability to combine learned patterns in flexible ways. A model can write a story in an unusual style, design an image of a fictional place, compose music with a particular mood, or produce code for a new problem. These outputs may be original in the practical sense that the exact result did not previously exist. Yet the system's ability to generate them depends on the structures it learned from existing data.
This has led to continuing debates about authorship, copyright, and the role of human creativity. Questions include how training data should be collected, whether creators should be compensated when their work contributes to model training, and who should own or control AI-generated content. These issues are legal and social as well as technical, and different jurisdictions may treat them differently.
As generative AI improves, the line between generation and broader forms of problem solving is also becoming less clear. A model may generate a plan, use external tools, inspect the results, revise its approach, and continue until it completes a larger task. In these systems, content generation becomes one part of a wider process that may include reasoning, retrieval, calculation, and action.
So, how does generative AI work? At its core, it learns statistical structure from large amounts of data and uses that structure to predict and construct new outputs. Text models generate sequences of language, image systems build visual content from learned patterns, audio models create sound over time, and video systems combine visual generation with temporal consistency. Multimodal models bring several of these capabilities together.
The most important point is that convincing generation and genuine understanding are not identical. Generative AI can produce highly useful, original, and sophisticated content because it has learned extraordinarily complex patterns, but its outputs still require appropriate evaluation. As these systems become more capable, their value will depend not only on how realistic or fluent their creations appear, but also on how reliably they can be connected to accurate information, human judgment, and clear safeguards.